In short
Catalog-backed chat should expose meaningful retrieval stages instead of pretending completion can be measured as a percentage. A resilient design streams updates when possible, falls back cleanly when it cannot, enforces a hard deadline, propagates cancellation, and records distinct terminal outcomes for users and operators.
Our first version failed in a familiar way: it returned a useful product answer after a few seconds, but the chat looked dead while it worked. The search had not failed. The interface had failed to explain the wait.
That distinction matters in catalog-backed chat. Nielsen Norman Group describes three response-time limits: about 0.1 seconds feels immediate, about one second preserves a user's flow, and around ten seconds is the limit for keeping attention without feedback. A catalog turn that takes three to five seconds sits in the awkward middle. It is reasonable system latency, but long enough for silence to look like a broken request.
Making retrieval faster is still valuable. It is not a complete answer. Live catalogs introduce variable work: ambiguous language, references to earlier products, filters, availability checks, ranking, and response construction. We needed the wait to remain understandable even when it could not remain under a second.
Why Silence Fails Before Search Does
A user sees one turn. The system sees a pipeline. When the interface shows only an unchanged typing bubble, it collapses every healthy intermediate state into the same visual state as a stalled connection. The longer that ambiguity lasts, the more likely the user is to retry, rephrase, navigate away, or assume the answer will never arrive.
Progress feedback does not reduce latency, but it reduces uncertainty. Nielsen Norman Group's guidance on progress indicators makes the same basic point: feedback helps people understand that the system received the request and is still working. That is especially important after the roughly one-second boundary, when a response no longer feels continuous.
The useful design question is therefore not only, “How fast is search?” It is also, “What can the interface truthfully say while search runs?” This is the approach HoverBot uses for catalog-backed chat, and it describes the design we committed to and run.
The same principle applies beyond products. Good knowledge management for AI chatbots includes the user experience around retrieval, not just the quality of the material retrieved.
Report Stages, Not a Percentage
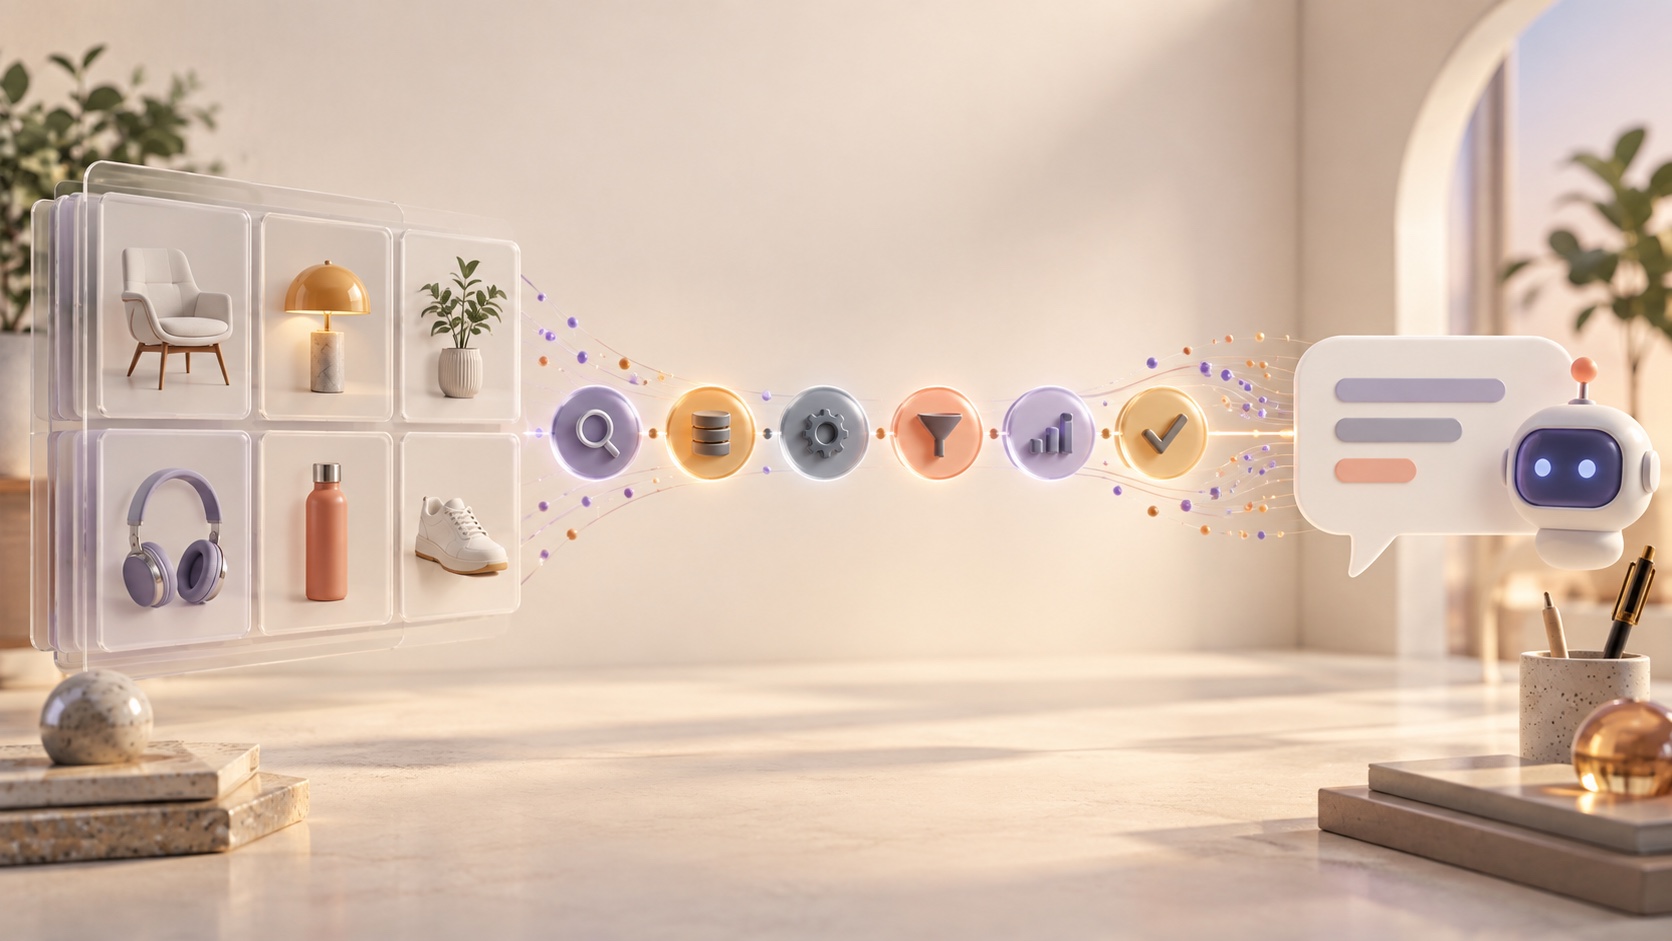
We settled on six stages that match what a user can understand about a catalog turn:
- Understand the request. Extract intent, constraints, comparison criteria, and whether clarification may be needed.
- Resolve references to earlier products. Work out what “the second one,” “that cheaper model,” or a pronoun refers to in the conversation.
- Search. Query the live catalog using the interpreted constraints and conversational context.
- Validate. Confirm that candidates still exist, belong in scope, and satisfy constraints that search alone cannot guarantee.
- Rank. Order valid candidates by relevance and the rules the experience is meant to apply.
- Build the answer. Turn the result into readable text, product choices, or a focused clarification question.
These stages are a reader-facing model, not a promise that every turn follows six equal steps. A simple browse may not need reference resolution. A query with no usable candidates may stop after validation. Several stages may finish too quickly to display. Progress should report work that is actually happening, not force every request through a theatrical sequence.
We avoided percentages because catalog retrieval has no stable denominator. Search might dominate one turn while validation dominates another. Ranking can be trivial for three candidates and expensive for many. A bar at 70 percent would suggest knowledge the system does not have. A label such as “Checking product information” makes a smaller and more honest claim.
Stream When Every Layer Can
Stage updates are useful only if every party on the path can carry them: the catalog service, the application server, any intermediary, and the chat client. When they can, server-sent events are a good fit. The updates are small, ordered, and travel from server to client while one operation remains open.
When any party cannot stream reliably, degrade to an ordinary request and response. Keep the typing indicator visible, use generic text, and deliver the same final answer. Do not treat missing progress support as a search failure.
This fallback is essential for embedded chat. Host pages, proxies, mobile containers, and deployment layers do not all behave alike. If streaming is required for correctness, a presentation enhancement becomes a new availability dependency. If the plain path has different answer or error semantics, the system now has two products to debug. We kept one catalog operation with two delivery modes.
Capability checks also need to be end to end. It is not enough for the backend to emit updates if the client discards them, or for the client to expect them when an intermediary buffers the response. Select streaming only when the full route supports it. Otherwise choose the fallback before starting work, when possible.
Deadline, Cancellation, and Terminal Outcomes
Progress can make a wait tolerable. It must not make the wait unbounded. Put a hard wall-clock deadline around the entire turn, including setup, retrieval, validation, ranking, and response construction. An illustrative ceiling might be around ten seconds for an interactive flow, but the right deadline depends on the product experience and the cost of abandoning work. The important property is that stage activity does not reset it.
Cancellation must also stop the work, not merely hide the typing indicator. Carry a cancellation signal from the widget through the application and into every operation that can still consume network, compute, or database capacity. When a user leaves or cancels, stop reading, stop downstream work where possible, and prevent a late answer from appearing in a newer conversation state.
We learned to classify terminal outcomes explicitly:
- Cancelled. The user or client chose to stop the turn.
- Timed out. The operation exceeded its deadline.
- Failed. A transport, service, parsing, or application error prevented completion.
- Finished without a result. The pipeline completed normally but found nothing usable.
- Succeeded. The turn produced a result or a valid clarification.
These distinctions are operational, not cosmetic. A cancellation should not inflate an outage alert. A timeout points toward capacity or dependency latency. A finished search with no result may indicate catalog coverage, query interpretation, or a genuinely empty set. If all three become “search failed,” on-call engineers must reconstruct intent from traces during an incident.
What the Widget Shows
The widget keeps a familiar typing indicator and changes its text as stages arrive. The copy stays short: “Understanding your request,” “Searching the catalog,” “Checking product information,” “Ranking the best matches,” and “Preparing the answer.” It does not expose service names, query syntax, or internal workflow terms.
If updates go quiet, the widget replaces the last stage with a fallback line such as “This is taking a little longer. Still working on it.” The switch should happen only after a meaningful pause, using an illustrative interval suited to the interface rather than pretending there is one universal timer. The fallback covers sparse emitters, buffered delivery, and the plain request and response path.
The final state still matters more than the animation. On cancellation, remove the pending state without showing a backend error. On timeout or failure, say the request could not be completed and offer a sensible retry. When the search finishes without a result, say that no matching products were found and invite the user to relax a constraint. Those outcomes should never share one vague message.
This is also a useful constraint for customer service automation in 2026: automation should make system state legible when the work is not immediate.
What We Gave Up
We gave up transport simplicity. A streaming path and a plain path both need tests, observability, and consistent terminal behavior. Capability negotiation adds another place for integration mistakes. Long-lived responses can be buffered or dropped by infrastructure that handles ordinary requests without trouble.
We also gave up visual smoothness. Some honest stages flash past. Others remain visible for several seconds. We chose not to add artificial delays just to make the sequence look polished. Minimum display times make the system slower and turn status into choreography.
Finally, progress labels expose only a coarse model. They help a user understand the wait, but they do not explain every retry, cache lookup, or parallel branch. That is intentional. Detailed execution belongs in telemetry. The interface needs a truthful summary, not a live trace.
The Practical Rule
A catalog-backed chat should be fast when it can be and legible when it cannot. Report real stages, stream them only when the entire path supports it, preserve a plain fallback, enforce one hard deadline, and make cancellation reach the work itself.
This pattern does not make retrieval faster. It keeps normal latency from masquerading as failure, and it gives operators enough information to tell an abandoned request from a broken system.
Want to see catalog-backed chat with progress streaming? Request a demo and we will walk through the catalog skill configuration.
Request a demoFrequently asked questions
- How should a chatbot show progress while searching a product catalog?
- Show short status text for the stage currently running, such as understanding the request, searching the catalog, validating products, ranking matches, or building the answer. Keep a typing indicator visible, and replace the stage text with a calm fallback line if updates go quiet. Do not imply that the system knows an exact completion percentage.
- Why use stages instead of a percentage progress bar?
- Catalog retrieval has no stable denominator. Search, validation, ranking, and answer construction vary with the query, catalog, and backend state. A percentage would be estimated and may stall or jump. Stage labels make a narrower, honest claim: they tell the user what kind of work is happening now, without pretending to predict when it will finish.
- Should catalog progress streaming be required for every chat client?
- No. Stream progress only when the service, intermediary, and client can all carry and consume it reliably. Otherwise use an ordinary request and response and keep a generic typing message visible. The final answer and error semantics should remain the same in both modes, so progress is an enhancement rather than a dependency for correctness.
- How should catalog search cancellation and timeouts work?
- Apply one wall-clock deadline to the whole operation and propagate cancellation through every active layer, including retrieval, validation, and ranking. Record cancelled, timed out, failed, finished without a result, and successful completion as distinct outcomes. That separation prevents user cancellation from looking like an outage and helps on-call engineers diagnose the actual failure mode.
Sources
- Progress Indicators Make a Slow System Less Insufferable · Nielsen Norman Group
- Response Times: The 3 Important Limits · Nielsen Norman Group
- Server-sent events · WHATWG HTML Living Standard
About the author
Founder & CEO at HoverBot
Founder of HoverBot, where he leads product strategy and applied AI architecture, and CTO and co-founder of WTFox.ai. Nineteen years in software engineering, most recently as Software Architect at Mercer, where he shipped HR chatbots and OCR claims processing on Azure AI, and as tech lead at Darwin and Technosoft SEA, after engineering roles at Sberbank, Veon, and Softline. Hands-on with architecture decisions, deployment operations, and benchmark-driven quality optimization. Based in Singapore.
- 19 years of software engineering, architecture, and engineering leadership
- Founder of two AI startups: HoverBot and WTFox.ai
- Applied AI: conversational systems, RAG pipelines, agentic workflows, and safety controls
- Enterprise AI delivery: HR chatbots and OCR claims processing on Azure AI at Mercer
- Led engineering teams of 10+ as tech lead and software architect
- Cross-industry: enterprise HR and benefits, banking, telecom, automotive, e-commerce and marketplaces
- Writes on AI chatbot architecture, agentic systems, and deployment patterns at vitaliks.me