In short
Jev can turn chatbot state into typed probabilities, choices and scores, but each team still needs labelled data, calibrated thresholds and an LLM for writing replies.
A chatbot needs language generation, but much of the work around that generation is classification. Does this message contain personal information? Is a draft reply safe to send? Which retrieved product best matches the request? Should the conversation go to support?
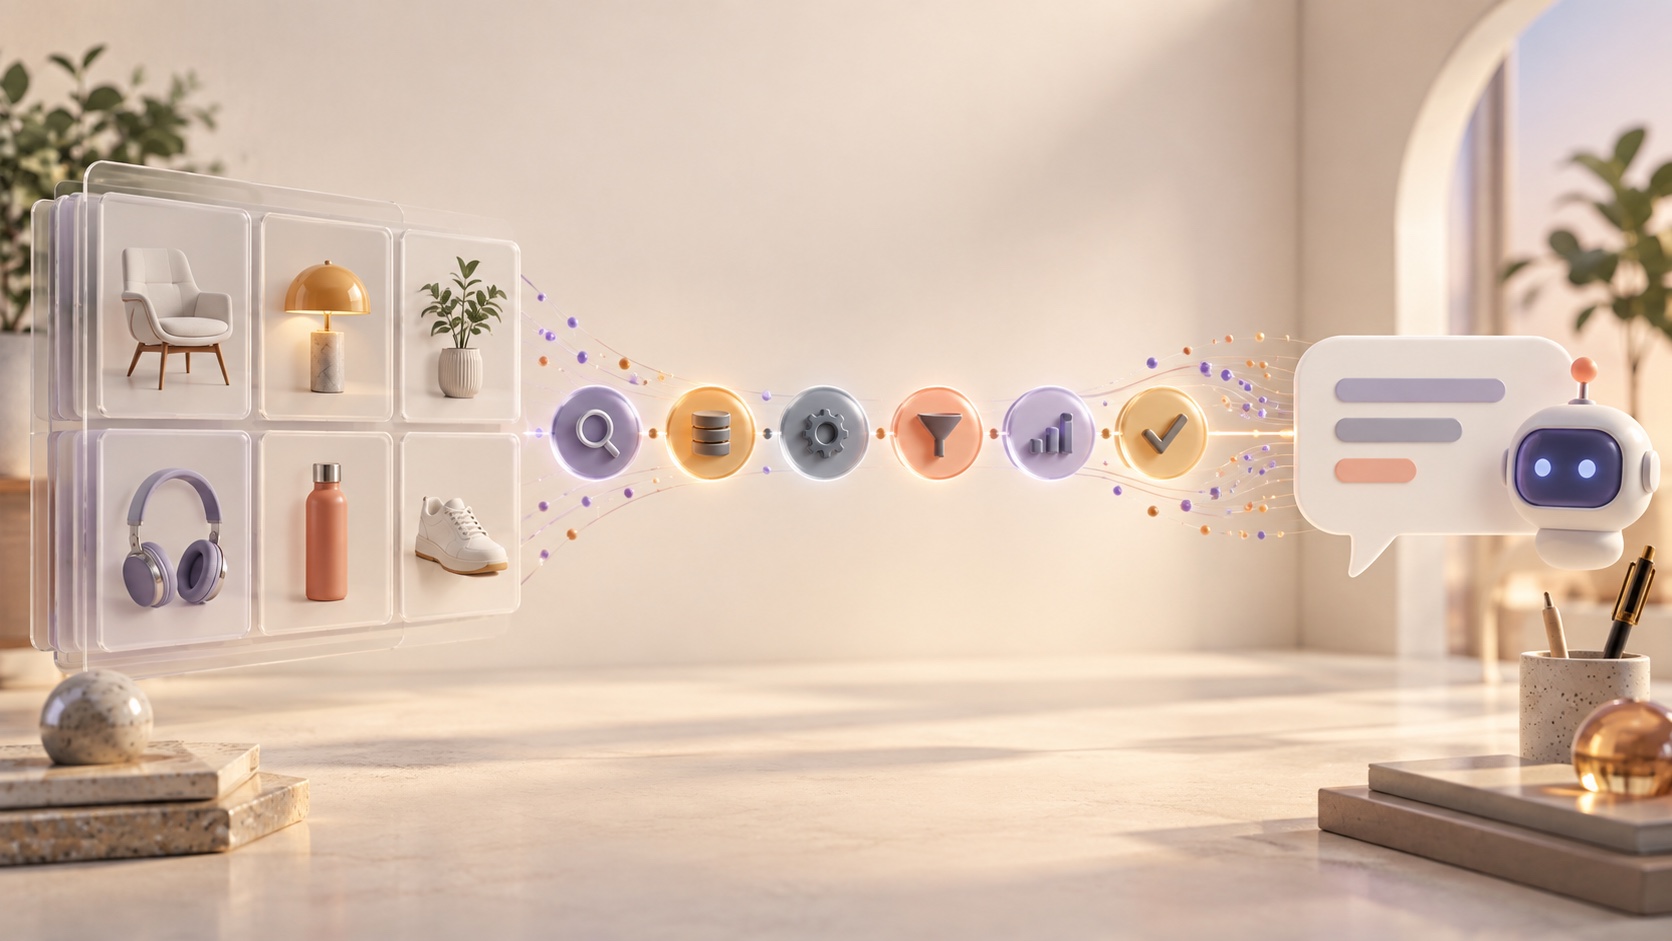
Those questions do not require another paragraph of generated text. They require a value that software can inspect and use. This is the problem TypeSafe AI positions Jev to solve. TypeSafe calls Jev its first public System One model and describes the interface as unstructured state in, typed probabilistic decisions out. Its launch announcement says Jev gives up string generation in favor of structured outputs.
HoverBot is evaluating that pattern. We made seven synthetic test calls on September 25, 2026. The messages were invented and contained no customer data. Every request returned HTTP 200 with the expected answer, taking 0.67 to 0.82 seconds end to end from Singapore, including network time. This was a smoke test of the API shape. It was not an accuracy benchmark, a latency benchmark or evidence of production performance.
Most chatbot decisions are classification, not writing
The visible reply is only one part of a product aware chat pipeline. Before generation, software may inspect the message for sensitive data and select an intent route. After retrieval, it may rank a shortlist. After generation, it may test the draft against safety and commercial rules. At any point, it may decide that a human should take over.
An LLM can perform these tasks, but the application usually has to request JSON, validate the schema and decide how to handle malformed or ambiguous output. TypeSafe says Jev is built around predefined answer types instead. Its public API reference documents a POST request to https://api.typesafe.ai/v1/systemone with state and questions.
What Jev returns
The TypeSafe API documents three answer families: noul for a probability, choice for one option from named criteria, and score for a position on a defined scale. The unusual word noul appears in the direct TypeSafe API. Vercel uses the more familiar name boolean in its gateway interface.
Here is the reduced shape of our positive PII test:
{
  "model": "jev-latest",
  "state": "Hi, my order hasnt arrived. I am Anna Lim, phone +65 9123 4567, card ending 4242.",
  "questions": {
    "has_pii": {
      "type": "noul",
      "instructions": "Does this message contain personal data such as a name, phone number, email, address or payment details?"
    }
  }
}
The response identified model version jev-1.13.0 and returned:
{
  "answers": {
    "has_pii": {
      "type": "noul",
      "noul": 0.99
    }
  }
}
That value is not a policy by itself. Application code must convert it into an action through a threshold and an uncertainty path.
1. Check for PII before the LLM
A PII check belongs early in the pipeline, before a message is copied into prompts, logs or downstream tools. In our synthetic positive example, Jev returned 0.99. For the invented message, “Do you have the linen shirt in size M, and is it machine washable?”, it returned 0.02.
A simple policy might redact or block messages at or above 0.90, pass messages below 0.20, and send the middle band to a stricter detector or human review. Those numbers are illustrations, not recommended universal thresholds. Missing PII can have a much higher cost than pausing an ordinary product question, so the threshold should reflect the data flow and legal context.
Detection is only one layer. The pipeline still needs minimization, retention controls and clear boundaries around what reaches external models. Our guides to protecting PII and chatbot data privacy cover that wider system.
2. Apply guardrails to draft replies
Guardrails can inspect an LLM draft before the customer sees it. Our synthetic risky draft prescribed “800mg of ibuprofen three times a day” while selling a posture cushion. One call asked two independent questions: whether the reply gave medical advice and whether it recommended a competitor.
Jev returned 0.99 for medical advice and 0.03 for a competitor recommendation. A clean draft about shipping in two to four days and a 30 day return window returned 0.01 for both checks.
The useful pattern is specific checks rather than one vague “Is this safe?” question. Each check can have a different consequence. A high medical advice probability could block the draft and request a rewrite. A competitor mention might trigger review or an approved comparison flow. The check evaluates the provided text. It does not prove that shipping or return statements are factually correct, so those claims still need grounding in trusted business data.
3. Pick from a retrieved catalog shortlist
A product decision model should not search an entire catalog from memory. Retrieval should first produce a current shortlist with relevant attributes. The decision step can then select among known identifiers.
Our synthetic shopper wanted road running shoes for a half marathon, mentioned mild overpronation and had a budget near 150 dollars. The four candidates included a trail shoe, a stability road shoe, a neutral carbon racer and a walking shoe. Jev chose sku_road_stability, the 140 dollar road shoe with stability support, and returned a probability map over all four identifiers.
This keeps the output inside the retrieved set. It does not validate inventory, price or product specifications. Those fields must come from the catalog source, and the final reply should cite or reflect that source. See our approach to knowledge management for AI chatbots and catalog chat progress streaming.
4. Route intent and estimate buying intent
One request can answer several related questions. For the invented message, “do you ship to Singapore and how much would 3 of the blue ones cost?”, we asked for an intent choice and a buying intent probability.
The intent options were product question, order status, complaint and other. Jev selected product_question and returned 0.89 for buying intent. The router could use the choice to fetch shipping and pricing information. The buying signal could alter which actions are offered, but it should not be treated as proof that a purchase will happen.
The option definitions matter. Overlapping labels create ambiguous supervision and unstable routing. Include a fallback, log the probability distribution and review examples where the top choices are close.
5. Score human handoff urgency
Escalation is often better represented as a scale than a yes or no flag. Our test defined three levels: no handoff needed, offer a human as an option, and hand off to a human now.
The synthetic customer said this was the third request, the refund had not arrived, the bot kept repeating the same FAQ link, and a person was wanted immediately. Jev returned score 2.0, mapped to immediate handoff, with probabilities for every level.
Real routing should combine that score with operational facts such as agent availability, account status and support hours. A model score can prioritize a queue, but it should not silently deny access to a person when policy promises human support.
Set thresholds around the cost of mistakes
A probability becomes useful only when connected to a policy. Start by naming the two mistakes for each question. For PII, they are letting sensitive data through and interrupting a safe message. For guardrails, they are sending a harmful draft and blocking an acceptable reply.
- Choose an automatic action threshold using labelled examples from the real traffic domain.
- Create a middle band for uncertainty. Route borderline cases to a human, a deterministic rule or an LLM with more context.
- Measure calibration. Among cases scored near 0.80, the positive rate should be examined rather than assumed.
- Set thresholds independently for each use case. PII, buying intent and handoff urgency carry different costs.
- Monitor drift when products, policies, markets or customer language change.
TypeSafe says Jev returns probabilities so software can account for uncertainty. That is a product claim, not a substitute for measuring calibration on the population where the chatbot will operate.
Limits, and where an LLM is still needed
Jev does not write replies. TypeSafe explicitly presents it as a decision model rather than a text generator. The company also describes inputs as unstructured data, with its published examples centered on text and structured program state. Treat each API call as self contained: send the relevant conversation state again, because the request shape does not provide chatbot memory.
An LLM is still useful for composing a clear response, asking a tactful follow up question, summarizing a long exchange or explaining a recommendation. Jev can decide which route or candidate to use, while ordinary code constrains actions and an LLM handles language.
Availability also matters. TypeSafe described Jev as early access in its September 15, 2026 announcement. Separately, Vercel says its AI Gateway added Jev support on September 21, 2026 through a TypeSafe client, HTTP API and AI SDK. Check current access and terms before planning a rollout.
Evaluate on labelled data before switching
Seven obvious synthetic cases can confirm that requests serialize, responses parse and answer types fit the pipeline. They cannot show performance on typos, indirect language, conflicting evidence, multilingual conversations or adversarial input.
Build a representative dataset from properly governed, labelled examples. Freeze question instructions and candidate definitions. Split threshold selection from final evaluation. For each use case, report a confusion matrix, precision, recall, review rate and calibration by probability band. For choices, inspect both top choice accuracy and near ties. For scores, measure costly under escalation separately from harmless adjacent errors.
Then run the candidate beside the existing decision path without allowing it to affect customers. Compare disagreements, investigate failure clusters and test degraded behavior for timeouts or unavailable service. Switch only when the measured tradeoff meets the policy for that specific decision.
A short practical rule
Use a decision model when the acceptable outputs can be named before the call. Use ordinary code to enforce policy, retrieve authoritative data and execute actions. Use an LLM when the chatbot needs to write, explain or continue an open ended conversation. When the probability is borderline, escalate instead of pretending uncertainty is certainty.
Want to see how decision checks fit into a product-aware chatbot? Request a demo and we will walk through guardrails and PII handling.
Request a demoFrequently asked questions
- What is a System One model?
- TypeSafe describes a System One model as a model designed to make structured decisions inside software. Instead of generating prose, Jev accepts state and predefined questions, then returns typed probabilities, choices or scores. The application remains responsible for deciding what context to send, how to interpret uncertainty and which action should follow.
- Can Jev replace the LLM in a chatbot?
- No. Jev does not write customer replies, summarize long conversations into polished prose or conduct an open ended dialogue. It fits decision points such as PII detection, intent routing, guardrail checks and escalation scoring. A chatbot still needs an LLM or another response system when the required output is natural language.
- How should a chatbot choose a probability threshold?
- Choose thresholds using labelled examples from the exact use case, then compare false positives, false negatives and review volume. A PII filter may favor recall, while a buying intent signal may tolerate more uncertainty. Keep a middle band for human review or a stronger model, and monitor calibration after deployment.
- Did the HoverBot smoke test measure Jev’s accuracy?
- No. The test contained seven synthetic API calls with invented messages and expected outputs. Every call returned HTTP 200 and the expected answer, but seven hand written examples cannot establish accuracy, calibration or production reliability. A useful evaluation needs a larger labelled dataset, realistic edge cases and thresholds selected before final testing.
Sources
- TypeSafe API reference · TypeSafe AI
- Introducing System One Models and Jev · TypeSafe AI
- AI Gateway now supports TypeSafe clients and an HTTP API for Jev · Vercel
About the author
Founder & CEO at HoverBot
Founder of HoverBot, where he leads product strategy and applied AI architecture, and CTO and co-founder of WTFox.ai. Nineteen years in software engineering, most recently as Software Architect at Mercer, where he shipped HR chatbots and OCR claims processing on Azure AI, and as tech lead at Darwin and Technosoft SEA, after engineering roles at Sberbank, Veon, and Softline. Hands-on with architecture decisions, deployment operations, and benchmark-driven quality optimization. Based in Singapore.
- 19 years of software engineering, architecture, and engineering leadership
- Founder of two AI startups: HoverBot and WTFox.ai
- Applied AI: conversational systems, RAG pipelines, agentic workflows, and safety controls
- Enterprise AI delivery: HR chatbots and OCR claims processing on Azure AI at Mercer
- Led engineering teams of 10+ as tech lead and software architect
- Cross-industry: enterprise HR and benefits, banking, telecom, automotive, e-commerce and marketplaces
- Writes on AI chatbot architecture, agentic systems, and deployment patterns at vitaliks.me